From Intent to Data Product: Pipelines, Agents & MCP

The challenge for most data teams isn’t a lack of ideas—it’s the time it takes to turn those ideas into something usable. In this session, Steffen Bischoff, Chief Architect Data at Qlik, follows a single dataset from a core system through its entire journey to becoming a governed data product. You’ll see pipelines created by describing intent instead of writing code, versioned in Git, then curated, quality-checked, and documented with the help of specialized agents. From there, the data product is made available to the AI tool of your choice through the Qlik MCP Server.
The Data Differentiator: Vanguard's Playbook for AI-Ready Data

Semantic layers and ontologies have moved from nice-to-have data modeling tools to the foundational engine required for enterprise AI. In this episode, Raman Tallamraju, Senior Director and Head of Enterprise Data Architecture and Engineering at Vanguard, breaks down how Vanguard is architecting its AI semantic layer to turn scattered institutional knowledge into reliable, agent-ready context. He shares why autonomous agents expose decades of hidden data debt, how to bridge domain-specific definitions like clients versus prospects, and how to balance building a unified semantic layer with a pragmatic, federated data operating model.

Confluent Cloud for Apache Flink: Engine for Mission-Critical, Real-Time Operational Systems and dbt/SQL-Native Home for Data Science and AI

Organizations today are under immense pressure to deliver on two critical fronts: building mission-critical, real-time operational systems and powering the next generation data science and artificial intelligence (AI) workflows with analytics-ready data. Historically, achieving both meant navigating a divided, complex architecture.

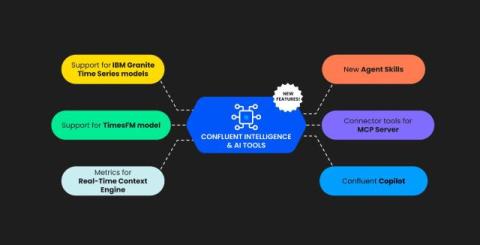
New in Confluent Intelligence and AI Tools: Making Agents Native to the Stream, Expanded Model Support, New Agent Skills, and Copilot

A customer writes in asking where their order is. The AI support agent checks the account, sees the order marked shipped, and sends a reply. The order was cancelled forty minutes ago. The agent wasn't wrong about anything it could see. It was reasoning over stale data that refreshes every six hours. This is why AI projects stall. Not because the models aren't capable, but because they lack AI-ready data and a reliable view of the current state of the business.

New in Confluent Cloud and WarpStream: Evolving the Data Streaming Platform for AI, Scale, and Control

In the last few months, Confluent has released over 70 new features to our data streaming platform, ranging from new connectors to better networking connectivity to entirely new ways to build streaming applications. We are not slowing down. Confluent’s DSP can do more, across every pillar, in ways that are more powerful, more complete, and more connected than ever before.

Snowflake RBAC: How to Manage Who Accesses What in Your Pipelines

Your data engineer just accidentally deleted the production customer table. Again. This scenario plays out in organizations worldwide, not because of malicious intent, but because of poorly configured access controls. With data breaches and compliance violations, managing who can access what in your Snowflake data warehouse isn't optional: it's essential.

Demo: Real-time anomaly detection and forecasting, Real-Time Context Engine for AI agents, and more

What's new in Q3'26: Real-time anomaly detection and forecasting with IBM Granite Time Series models and Google TimesFM model, upserts for Real-Time Context Engine to maintain fresh context for AI, and lightning queries to instantly serve the current state of the business for operational apps, analytics, and more.