We collect the latest Development, Anaytics, API & Testing news from around the globe and deliver it direct to your inbox. One email per week, no spam.
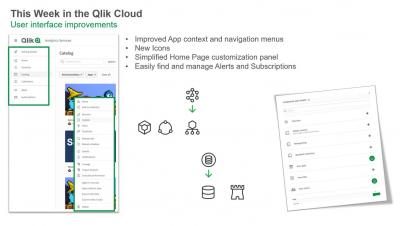
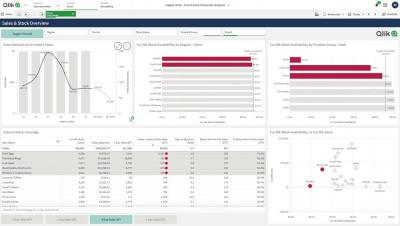
Prevent lost sales with automated machine learning for out-of-stock prediction and trigger timely stock alerts while automating replenishment processes. Find out how to do all this and more with Qlik Cloud Platform.
We have closed a $50 million Series D round of funding, led by Third Point Ventures with participation from Bridge Bank and existing investors that include Menlo Ventures, Point72 Ventures, GCV Capital, and Harmony Capital. Kunal Agarwal, CEO and Co-Founder, shares what this funding means for you.
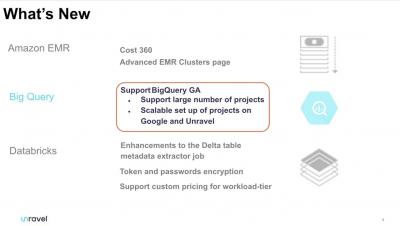
Unravel is a DataOps observability platform that enables your data teams to optimize the cost of your data operations intelligently, run faster data pipelines, and troubleshoot mission-critical applications. Watch this video to discover what’s new in Unravel Data 4.7.5.0 release.
Introduced in 9.7 as the simplest way to ask questions of your data, Yellowfin 9.8 delivers exciting updates to Guided NLQ, and additional improvements to our report builder. The latest release makes Guided NLQ even more powerful and simpler to use, with new question types (Cross-tab), more intuitive questions with field synonyms and default date periods, and protection against long-running queries - in addition to faster report building.
The Cloudera Applied Machine Learning Prototype (AMP) for continuous model monitoring acts as a customizable template for your data science team to quickly build an accurate way to track drift.
For DataOps teams, job failures are common. But finding the issue is (traditionally) where things get even worse. It can take hours or days to troubleshoot a job failure. Unravel Data provides a single view where DataOps teams can locate exactly where–and why–a job failed, along with precise recommendations to troubleshoot the error. DataOps teams are now able to both diagnose and troubleshoot job failures in minutes instead of days or weeks.
Data pipelines fail all the time for a variety of reasons; service downtime, data volume fluctuations, etc. Diagnosing these failures manually is very difficult and time consuming. Unravel Data allows DataOps teams to troubleshoot pipeline failures automatically – showing exactly where and why a pipeline failed, and precise recommendations to remedy the issues. Using Unravel, DataOps teams can now diagnose and fix data pipeline failures in a fraction of the time.
To ensure that jobs are running optimally, DataOps teams need to look at the detailed code. But DataOps teams don’t have the right tools to easily examine problematic code - or a simple path to optimizing it. With Unravel Data, DataOps teams can quickly troubleshoot applications that are throwing errors - all the way down to a specific line of problematic code. All in a single view.
DataOps teams need to understand where costs are going. But the reports provided by cloud vendors aren’t very granular - and they only get the reports after excess costs have been racked up. Unravel allows DataOps teams to understand where costs are going at a detailed level: by user, by service, by department. This information is captured and available as soon as a cluster is detected – allowing DataOps teams to take action and optimize in real time.