Co-author: Mike Godwin, Head of Marketing, Rill Data Cloudera has partnered with Rill Data, an expert in metrics at any scale, as Cloudera’s preferred ISV partner to provide technical expertise and support services for Apache Druid customers. We want Cloudera customers that rely on Apache Druid to know that their clusters are secure and supported by the Cloudera partner ecosystem.
The dynamic and interconnected world of global ecommerce, crypto currencies, and alternative payments places increased pressure on anti-financial crime measures to keep pace and transform alongside these initiatives. Consumers worldwide are projected to use mobile devices to make more than 30.7 billion ecommerce transactions by 2026, a five-fold increase over the 6.1 billion predicted for 2022.
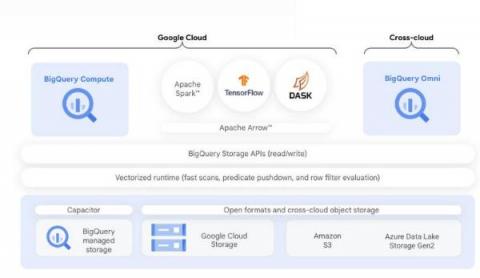
BigQuery is Google Cloud’s fully managed serverless data platform that supports querying using ANSI SQL. BigQuery also has a data lake storage engine that unifies SQL queries with other open source processing frameworks such as Apache Spark, Tensorflow, and Dask. BigQuery storage provides an API layer for OSS engines to process data. This API enables mixing and matching programming in languages like Python with structured SQL in the same data platform.
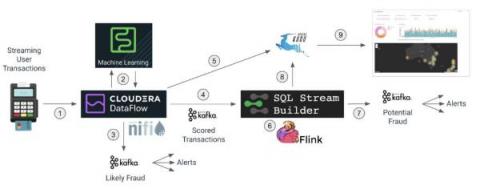
In part 1 of this blog we discussed how Cloudera DataFlow for the Public Cloud (CDF-PC), the universal data distribution service powered by Apache NiFi, can make it easy to acquire data from wherever it originates and move it efficiently to make it available to other applications in a streaming fashion.
Apache Kafka is an open-source distributed event streaming platform used by thousands of companies for high-performance data pipelines, streaming analytics, data integration, and mission-critical applications. Administrators, developers, and data engineers who use Kafka clusters struggle to understand what is happening in their Kafka implementations.
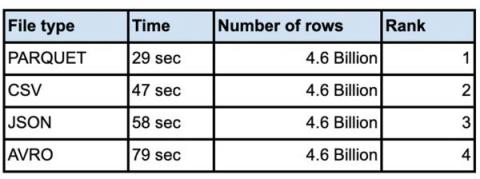
It is not unusual for customers to load very large data sets into their enterprise data warehouse. Whether you are doing an initial data ingestion with hundreds of TB of data or incrementally loading from your systems of record, performance of bulk inserts is key to quicker insights from the data. The most common architecture for batch data loads uses Google Cloud Storage(Object storage) as the staging area for all bulk loads.