Systems | Development | Analytics | API | Testing

Backpressure in AI streaming: change how tokens move, keep each response one message

Backpressure in AI streaming can build anywhere from inference to the client, but delivery is where handling it can change the response itself. The three usual approaches there (buffering, batching, and rewriting a stored record) can change how the response is stored, or what storing it costs. Anyone who joins mid-answer then gets fragments to stitch together, or your database pays for a full write at every flush.
Resumable token streaming: why AI streams break on reconnect

Refresh the page, lose signal, switch tabs. Users expect the AI conversation to still be there when they return, with the answer picking up where it left off. Resumable token streaming makes that possible: a returning client catches up with the in-progress response instead of starting over. Making a stream resumable is an architecture decision. Starting generation, storing the response, and delivering it need to happen in separate parts of your stack.

What a room of engineers asked me about realtime resilience

I spoke about Ably's approach to resilience at the AWS Cloud Resilience Roadshow in Dublin on 22 September 2026, and the questions afterwards covered CDNs, regional failover, outages, message ordering, and capacity. They got me reflecting on which parts of our approach are common across the industry, which are less so, and how choices made early, well before my time at Ably, have put us in a strong position today.

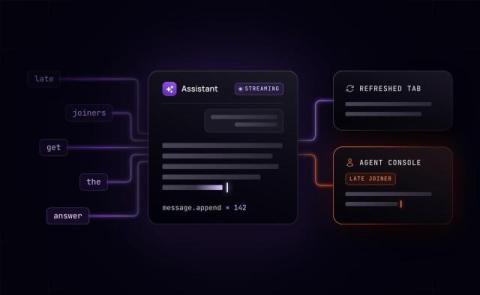
A token is not a message: stop storing AI responses like event logs

How you store a streamed AI response decides what a client sees when the client joins partway through. A human agent taking over a support conversation, a refreshed browser, and a second device all need the response generated so far, and depending on how the response was stored, that late joiner gets the full response, fragments, or nothing. This article compares four common ways to store a streamed response, what each one gives a late joiner, and what each one costs your team.

WebSockets vs Server-Sent Events: how to choose the right one for production

WebSockets and Server-Sent Events (SSE) solve the same immediate problem: getting data from a server to a browser without the client asking for it first. Most comparisons stop at how their connection types and browser support compare, to help you decide which one to use. This one covers that ground too, but goes further, into what neither protocol solves for you and whether to build that yourself or hand it to a managed platform.

Why WebSockets beat SSE for AI streaming at scale

Picture a support agent mid-refund: it has pulled the order, flagged the tool call, and is one approval away from processing it. Then the user needs to approve it. On Server-Sent Events (SSE), there's no channel for that approval to reach the agent, because the connection only carries data one way - from server to client. A WebSocket keeps that connection open in both directions instead, so the approval could reach the agent the moment it's given.

Why WebSocket ordering breaks down once you're in production

WebSocket guarantees message order, but only within a single, open connection. When that guarantee breaks in production and not in local testing, the cause is almost always one of four things: The first is a genuine one-time fix. The other three are infrastructure you commit to operating, not patches you apply once. Deciding which situation you're in, and what to do about it, is what this piece covers.

Raw WebSockets for AI streaming: when patching stops paying off

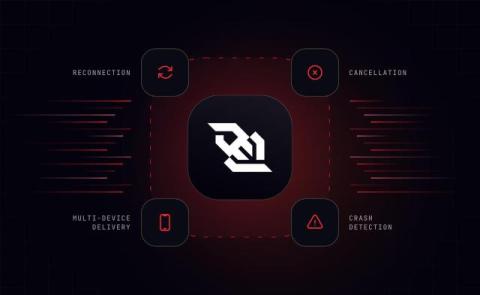
Raw WebSockets drop connections, lose track of canceled responses, and don't natively reach a second device. If your AI streaming feature has been in production for a while, you've probably already built a fix for at least one of these and found another one waiting. Reconnection, cancellation, multi-device delivery, and crash detection are the four problems raw WebSockets leave for you to solve, and each is its own piece of infrastructure to build. Solve one, and the other three remain unsolved.

Add resumable streaming and reliable tool calling to your OpenAI agent

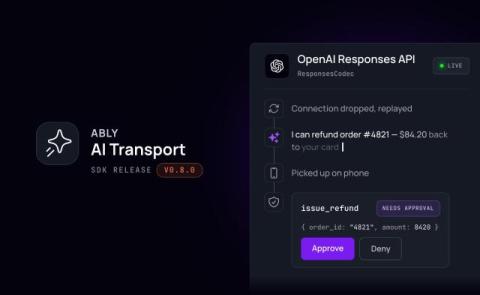
If you build an agent against OpenAI's Responses API then the simplest way to get output to the user is streaming over HTTP/SSE. If the user refreshes the page, loses connection, switches devices, or needs to approve a tool call, then there's nothing in the API to help you. AI Transport is Ably's session layer for agent-to-user conversations. An agent built on it gets resumable streams, multi-device sessions, and approval gates that wait for a human user, without deploying additional infrastructure.

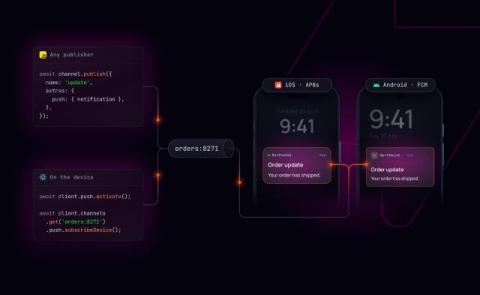
Ably Pub/Sub now supports React Native push notifications

Until now, sending push notifications to a React Native app with Ably meant registering devices manually through the push admin API, usually from a server. The new plugin moves activation where it belongs: onto the device. We've added first class support for React Native apps receiving push notifications through the Ably PubSub JavaScript SDK.