Systems | Development | Analytics | API | Testing

Observe Opaque Services With OpenTelemetry eBPF + proxymock

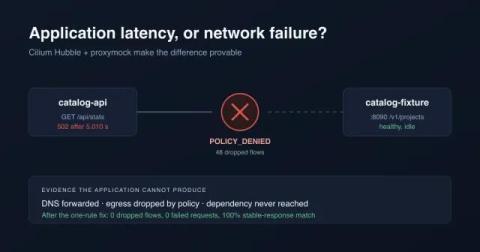
Every SRE team operates services it cannot see into: a vendor binary, an inherited legacy deployment, a container whose owning team dissolved two reorgs ago. The routes are undocumented, the dependencies are unknown, and when a request takes 130 milliseconds nobody can say whether that time is application work or a wait across a network boundary.
Sponsored Post

Two confident fixes missed this production bug

Every new signup posts a message to our Slack. The format is dull and reliable: Overnight this week one arrived like this: That trailing nothing was the entire incident. No error logs, no alerts. A returning user had signed up, our signup service had attached them to a tenant we deprovisioned back in December, and the only symptom in the whole company was a Slack message that ran out of words. Their company's email domain still pointed at the dead tenant, so instead of a fresh workspace they landed in a corpse: domain mapping still live, cloud infrastructure long gone. I'm on call this week, so I pulled the thread.
The Pod Was Cheaper. The Service Wasn't.

A smaller Kubernetes pod can lower allocation cost while completing less work. Green status codes and matching schemas can hide it. This walkthrough combines OpenCost allocation data with proxymock behavior and performance evidence. A candidate passes only when behavior and throughput hold while unit cost falls.

Diagnose Serial N+1 API Calls With Tempo + proxymock

One API request took 302 milliseconds. Nothing failed. CPU was mostly idle. The response was correct. The trace made the problem obvious: eight inventory calls, each waiting for the previous one. But the trace could not tell me why the application made eight calls, or whether changing their execution would preserve the response. It showed the shape of the wait, not the input that created it.

Flamegraphs Find It. Replay Proves It.

I made an API endpoint 13 times faster. Then I realized my first verification only checked the status, headers, and response schema. I had not checked the totals. I had made the bug faster. That is the problem with giving an AI coding agent one kind of evidence. A CPU profile can show where the application is slow, but not whether an optimization preserves behavior. A traffic replay can prove that behavior stayed stable, but not explain why the code burns CPU.

eBPF: Preventing Garbage HTTP Payloads When Reading Kernel Scatter-Gather Buffers

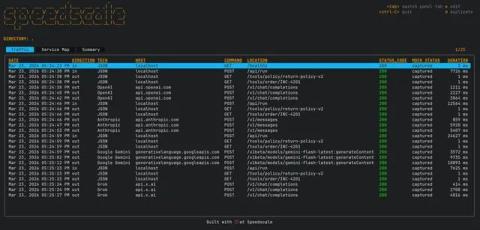
Recently someone on our team opened a traffic snapshot and found an HTTP request that was captured with our eBPF capture agent, nettap. Our protocol dissector parsed most of the response correctly, but that correctness ended once the response headers were processed. What they ended up with was a recording of an HTTP request/response where the response body was just an incorrect collection of garbage binary data when it should have been JSON text.
Sponsored Post

Build WireMock mappings fast from real traffic

I'm a big fan of service mocking. I've been working in and around software for about 25 years, and one thing never changes: when you sit down to work on your code, you almost never have everything available. The database, the third-party API, the message queue, the service two teams over. Something's missing. So you've got to stub it out or mock it out and keep moving.

AI writes code in seconds, but delivery still takes days

The pitch for AI coding was speed. Claude Code, Copilot, Cursor, whatever you’re running, they all generate business logic faster than you can review it. That part is real. But look at what happens after the code gets written and the numbers get ugly. CircleCI’s 2026 State of Software Delivery Report found AI drove a 59% increase in average throughput.