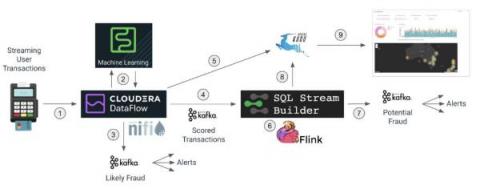
Fraud Detection With Cloudera Stream Processing Part 2: Real-Time Streaming Analytics

In part 1 of this blog we discussed how Cloudera DataFlow for the Public Cloud (CDF-PC), the universal data distribution service powered by Apache NiFi, can make it easy to acquire data from wherever it originates and move it efficiently to make it available to other applications in a streaming fashion.

What Is a Data Pipeline and Why Your Ecommerce Business Needs One

Our six key points on data pipelines include: Whether you’re a one-person show reselling items on an online marketplace or a large Ecommerce enterprise with hundreds of employees, these businesses share a common factor: both generate data. The size of your business can influence the amount of data you generate, sure. But any amount of data — if it’s not adequately accessible — is worthless. Every business, especially an Ecommerce business, needs a data pipeline.

Kafka best practices: Monitoring and optimizing the performance of Kafka applications

Apache Kafka is an open-source distributed event streaming platform used by thousands of companies for high-performance data pipelines, streaming analytics, data integration, and mission-critical applications. Administrators, developers, and data engineers who use Kafka clusters struggle to understand what is happening in their Kafka implementations.

MLOps World Toronto: MLOps Beyond Training Simplifying and Automating the Operational Pipeline

Most data science teams start with building AI models and only think about operationalization later. But taking a production-first approach and automating components is the key to generating measurable ROI for the business. In this talk, Iguazio’s co-founder and CTO, Yaron Haviv, explains how to simplify and automate your production pipeline to bring data science to production faster and more efficiently. He displays real live use cases while going through all the different steps in the process.

Performance considerations for loading data into BigQuery

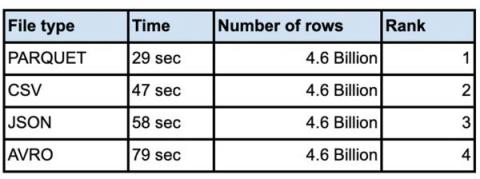
It is not unusual for customers to load very large data sets into their enterprise data warehouse. Whether you are doing an initial data ingestion with hundreds of TB of data or incrementally loading from your systems of record, performance of bulk inserts is key to quicker insights from the data. The most common architecture for batch data loads uses Google Cloud Storage(Object storage) as the staging area for all bulk loads.

People Were Skeptical of Data Warehouses. Now History Is Repeating.

This is a guest post by computer scientist Bill Inmon, recognized as the "father of the data warehouse." Bill has written 65 books in nine languages and is currently building a technology called textual ETL. Many years ago, there were no data warehouses. Most Ecommerce retailers relied on legacy systems with unintegrated data that couldn’t communicate with each other, resulting in data silos. Comparing data sets from these systems was almost impossible.