Systems | Development | Analytics | API | Testing

Digital Front Door Platforms: Key Features and How to Evaluate Them

‍ A digital front door platform connects patient-facing services with clinical and administrative workflows. Capabilities can include appointment scheduling, digital intake, patient communication, insurance verification, and payments. Coverage varies by vendor, product configuration, and supported electronic health record (EHR) integrations. Evaluating a digital front door (DFD) solution should cover complete workflows, integration depth, usability, security, and total operating costs.
Digital Front Door Strategy: A Framework for Health Systems

‍ A digital front door strategy coordinates patient access, engagement, and supporting health system workflows. It connects provider search, scheduling, registration, payments, and follow-up through integrated digital services. Effective digital front door (DFD) implementation requires EHR integration, accessible interfaces, secure data exchange, and clear operational ownership.

Convert Manual Test Cases to Automation Without Starting From Scratch

Your manual test library is more than documentation. It contains years of decisions about what your product should do, and how to tell when it doesn't. That knowledge is a valuable starting point for automation, not something you should have to recreate from scratch. The clearest example came up in a customer conversation. The head of quality at a fast-growing fintech told me his company pays an outside firm to run its manual regression, with a bill for every test executed.

How to Manage and Secure AI Coding Agents

AI coding tool spend is projected to top $13 billion in 2026, compounding at more than 60% a year. These agents don't just autocomplete a line of code anymore. They plan. They act. They call tools, run commands, and touch other systems on your behalf. This is pretty different from the assistant that used to live in your IDE sidebar. And that's exactly where the risk lives. An AI coding agent is software that writes, tests, and ships code independently. This level of autonomy earlier tools never had.

API + AI Summit 2026 Recap: Helping the World Move AI

That's a wrap on API + AI Summit 2026, Kong's biggest in-person event yet. The event brought together more than 1,000 engineers, architects, and leaders in Los Angeles to discuss running AI systems in production, tackle shared architecture challenges, and swap real-world insights. Recordings from this year’s event will be available in the coming weeks..

How to Use Shoulda Matchers with RSpec for Ruby on Rails

shoulda-matchers gives you one-line RSpec and Minitest matchers for common Rails behavior — it { should validate_presence_of(:name) } replaces a hand-written validation spec. Add gem "shoulda-matchers", "~> 8.0" to your Gemfile’s test group, then add the configuration block to spec/rails_helper.rb naming your test framework and library. Version 8 works with Rails 8.1 and rspec-rails 8.

Top ESG Software Companies for US Sustainability Reporting in 2026

Ask a sustainability team what slowed their last disclosure and the answer is usually mundane: inconsistent units, missing supplier records, emission factors applied three different ways across four business units, and no audit trail explaining why a number changed between drafts.

Jeff McMillan on How to Think About AI and Jobs

AI and jobs… the topic that’s top of mind for everyone, yet most organizations are asking the wrong questions. The conversation usually starts with cost cutting: how do we reduce headcount, automate repetitive tasks, trim the budget? Jeff McMillan, founder of McMillanAI, thinks that's the wrong frame entirely. He shares what the better questions are in this clip from The Data & AI Chief podcast.

Katalon AI Test Execution and False Passes

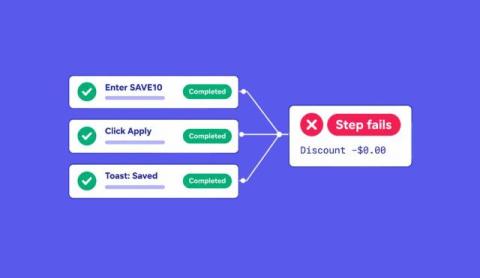
In a release test I published in July, Katalon’s AI runner reported seven cases passed and four failed. I could open the steps, inspect their screenshots, and watch the browser session. The failed rows showed which expectations broke. The passed rows deserve the same scrutiny: what had the agent observed before it called each step passed? An AI test runner has to perform the action and judge the outcome. A false pass is a passed verdict when the expected behavior did not occur.

10 Best Agentic QA Tools in 2026: Compare Workflows, Ownership and Cost

Your team has more changes to test, more environments to cover and less time to maintain regression suites. AI can help produce tests, but that introduces another workload: deciding whether those tests check the right behavior, whether a repair hides a defect and whether the evidence is enough to support a release. Agentic QA tools aim to take on more of that work, from planning and authoring to execution and failure investigation.