Systems | Development | Analytics | API | Testing

Sidekiq for Ruby on Rails: Setup, Jobs & Monitoring (2026)

Sidekiq is a background job framework for Ruby that processes jobs concurrently on threads, backed by Redis. In Rails, add gem "sidekiq", set config.active_job.queue_adapter = :sidekiq, enqueue with perform_async, and run the sidekiq process alongside your app server. Sidekiq 8 requires Ruby 3.2+ and Redis 7+. That answer covers the mechanics.
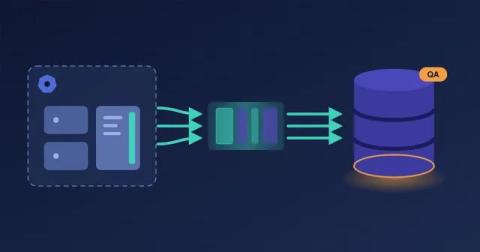
Load Test PostgreSQL Instantly using Production Recordings

The first PostgreSQL post ran on a laptop: a demo app, a Docker container, and the proxymock CLI. That is the fastest way to see the idea. It is also not where your database problems live. Your real query mix lives in the cluster, where a Java service with a connection pool, an ORM and a schema migration tool sends the statements nobody wrote by hand. This post deploys an open source banking app to Kubernetes and records the queries one of its services sends to PostgreSQL.

Best Healthcare EDI Software in 2026: 8 Platforms Compared

Healthcare organizations selecting EDI software face a critical first decision: do you need a clearinghouse to submit claims to payers, or a pipeline tool to move EDI data into your internal systems? This distinction shapes every subsequent technology choice. Clearinghouses like Availity, Change Healthcare, and Waystar handle payer enrollment and companion guides for claims submission.

Best Payroll Data Integration Tools for Benefits and 401(k) Providers

Every new plan sponsor brings a new data problem. ADP, Paychex, QuickBooks, and regional payroll providers can deliver census, deduction, and 401(k) contribution data in different layouts and file types. For a recordkeeper, TPA, or benefits provider supporting hundreds of employers, the challenge is not running payroll; it is reliably ingesting, validating, normalizing, and scheduling those incoming files without turning every new sponsor into an engineering project.

6 Best EDI to CSV and Excel Converters (834, 835, 837)

Electronic Data Interchange (EDI) files look like encrypted gibberish to the untrained eye: strings of asterisks, tildes, and segment codes like ISA, GS, ST, and BEG. These files follow X12 or EDIFACT standards that encode business transactions in a machine-readable format optimized for system-to-system communication, not human analysis.

Insurance API Integration: 7 Platforms for Connecting Carriers, TPAs, and Insurtechs

Insurance companies face a unique data integration challenge that most generic platforms cannot solve. Your benefits administration platform may connect via REST API to modern HR systems, while another partner still sends eligibility files over SFTP. Enrollment and eligibility workflows commonly use EDI 834 transactions, while claims workflows may involve X12 837 claims and 835 remittance data.

Why Infrastructure Platform Consumption Services Matter Now

During the past year, AI has transformed the infrastructure market. Organizations are rapidly expanding data center and cloud capacity to support new AI workloads, while facing growing pressure to manage cyber risk, control costs, and demonstrate measurable business value. As infrastructure investments increase, technology leaders must balance innovation with operational efficiency and financial accountability.

Wherever your config lives: Repo-stored and modular bitrise.yml

Most CI tooling makes you pick a side. Visual editing or code. Git as your source of truth or a decent place to edit. A config small enough for one file, or a modular structure your tooling flattens the moment you touch it. The Bitrise Workflow Editor does not ask you to choose. It meets your config where it lives. One file or forty, stored on Bitrise or in your repo. This post covers both, in that order.

Why Real Estate Data Doesn't Match: Causes and How to Fix It

Quick answer: Real estate data often differs across systems because MLS, PMS, CRM, and ERP platforms use different identifiers, schemas, formats, and update rules to represent the same property. Fixing it isn’t a one-time cleanup. It requires a reconciliation capability: identify candidate matches, normalize values, validate them, enrich missing fields, consolidate confirmed duplicates, resolve source priority when systems disagree, and monitor for new inconsistencies as records change.