Open Source Fractional GPUs for Everyone, Now Available from ClearML

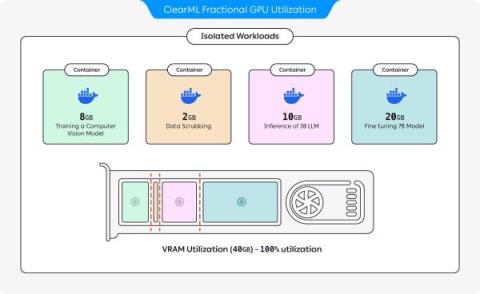
If you’ve been following our news, you know we just announced free fractional GPU capabilities for open source users, enabling multi-tenancy for NVIDIA GPUs and allowing users to optimize their GPU utilization to support multiple AI workloads as part of our open source and free tier offering.

Streams Forever: Kafka Summit London 2024 Keynote | Jay Kreps, Co-founder & CEO, Confluent

Join the Confluent leadership team as they share their vision of streaming data products enabled by a data streaming platform built around Apache Kafka. Jay Kreps, Co-creator of Apache Kafka and CEO of Confluent, will present his vision of unifying the operational and analytical worlds with data streams and showcase exciting new product capabilities. During this keynote, the winner and finalists of the $1M Data Streaming Startup Challenge will showcase how their use of data streaming is disrupting their categories.

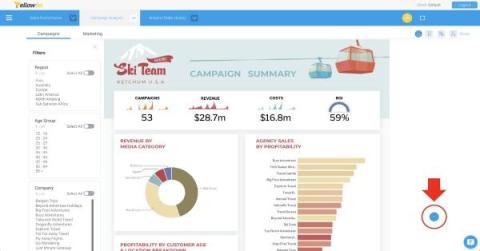
How to Add a 'Back to Top' Button to Your Yellowfin Dashboard

Welcome back to Yellowfin Japan’s ‘How to?’ blog series! In our previous blog, we went through how to create big number and vertical column charts in Yellowfin, and the many different charting options available in Yellowfin Canvas. Before we re-visit our regular series, we want to share a shorter dashboard walkthrough.

Exploring Apache Flink 1.19: Features, Improvements, and More

The Apache Flink® community unveiled Apache Flink version 1.19 this week! This release is packed with numerous new features and enhancements. In this blog post, we'll spotlight some of the standout additions. For a comprehensive rundown of all updates, don't forget to review the release notes.

Why a Solid Data Foundation Is the Key to Successful Gen AI

Think back just a few years ago when most enterprises were either planning or just getting started on their cloud journeys. The pandemic hit and, virtually overnight, the need to radically change ways of working pushed those cloud journeys into overdrive. Cost-effective adaptability was essential. And the companies that could scale up or scale down quickly were the ones that navigated the pandemic successfully. Migrating to the cloud made that possible.

Confluent Cloud for Apache Flink | Simple, Serverless Stream Processing

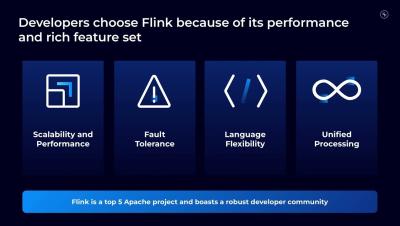
Stream processing plays a critical role in the infrastructure stack for data streaming. Developers can use it to filter, join, aggregate, and transform their data streams on the fly to power real-time applications and streaming data pipelines. Among stream processing frameworks, Apache Flink has emerged as the de facto standard because of its performance and rich feature set. However, self-managing Flink (like self-managing other open source tools like Kafka) can be challenging due to its operational complexity, steep learning curve, and high costs for in-house support.
The Confluent Q1 '24 Launch

The Confluent Q1 ’24 Launch is packed with new features that enable customers to build, connect, and consume intelligent data pipelines seamlessly and securely Our quarterly launches provide a single resource to learn about the accelerating number of new features we’re bringing to Confluent Cloud, our cloud-native data streaming platform.

New in Databox: Safeguard Your Data With Advanced Security Settings

As your company grows, so do the challenges of managing user access and data security. For many of us, it’s a common situation – the account that started with a few key players now has multiple users with different access levels. New team members join, roles evolve, team members move on to new opportunities, and sometimes external players (like contractors or clients) need temporary access to your account.